
Qwen (Alibaba)
Qwen3-VL-4B-Instruct
A 4B model by Qwen (Alibaba) that uses tools such as web search and reads images.
Tools Vision- Downloads
- 442,136 downloads last month
- Likes
- 75 likes
- Uploaded
- Uploaded 31 Oct 2025
Overview
From Qwen/Qwen3-VL-4B-Instruct- Parameters
- 4,437,815,808 (4.4B)
- Context length
- 262,144 tokens
- Architecture
- qwen3vl
- Task
- image-text-to-text
- Licence
- apache-2.0
- Released
- 11 Oct 2025
- Last updated
- 15 Oct 2025
This is Qwen's upload of Qwen/Qwen3-VL-4B-Instruct.
Tools
Uses tools, so web search and the browser work best with it.
Vision
Reads images: photos, screenshots, scanned pages.
Each version is the same model stored at a different precision: smaller files use less memory and lose a little quality.
| Version | File size | File | SHA-256 |
|---|---|---|---|
| Q4_K_M | 2.50 GB | Qwen3VL-4B-Instruct-Q4_K_M.gguf | |
| Q8_0 | 4.28 GB | Qwen3VL-4B-Instruct-Q8_0.gguf | |
| F16 | 8.05 GB | Qwen3VL-4B-Instruct-F16.gguf |
Vision add-on (needed to read images): mmproj-Qwen3VL-4B-Instruct-Q8_0.gguf, 454.0 MB
Architecture
From config.json in Qwen/Qwen3-VL-4B-Instruct- Model class
- Qwen3VLForConditionalGeneration
- Model type
- qwen3_vl_text
- Layers
- 36
- Hidden size
- 2560
- Attention heads
- 32
- Key/value heads
- 8
- Vocabulary
- 151,936
- Context length
- 262,144 tokens
- Weights
- bfloat16
- Vision encoder
- Included (vision_config)
Recommended settings
From generation_config.json in Qwen/Qwen3-VL-4B-InstructThe sampling settings the model's makers ship as its defaults.
- Temperature
- 0.7
- Top P
- 0.8
- Top K
- 20
- Repetition penalty
- 1
Papers and data
From Qwen/Qwen3-VL-4B-InstructPapers the model's Hugging Face page links to (the model's own report and papers it cites).
Qwen3-VL-4B-Instruct
Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.
This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities.
Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment.
Key Enhancements:
-
Visual Agent: Operates PC/mobile GUIs—recognizes elements, understands functions, invokes tools, completes tasks.
-
Visual Coding Boost: Generates Draw.io/HTML/CSS/JS from images/videos.
-
Advanced Spatial Perception: Judges object positions, viewpoints, and occlusions; provides stronger 2D grounding and enables 3D grounding for spatial reasoning and embodied AI.
-
Long Context & Video Understanding: Native 256K context, expandable to 1M; handles books and hours-long video with full recall and second-level indexing.
-
Enhanced Multimodal Reasoning: Excels in STEM/Math—causal analysis and logical, evidence-based answers.
-
Upgraded Visual Recognition: Broader, higher-quality pretraining is able to “recognize everything”—celebrities, anime, products, landmarks, flora/fauna, etc.
-
Expanded OCR: Supports 32 languages (up from 19); robust in low light, blur, and tilt; better with rare/ancient characters and jargon; improved long-document structure parsing.
-
Text Understanding on par with pure LLMs: Seamless text–vision fusion for lossless, unified comprehension.
Model Architecture Updates:
-
Interleaved-MRoPE: Full‑frequency allocation over time, width, and height via robust positional embeddings, enhancing long‑horizon video reasoning.
-
DeepStack: Fuses multi‑level ViT features to capture fine‑grained details and sharpen image–text alignment.
-
Text–Timestamp Alignment: Moves beyond T‑RoPE to precise, timestamp‑grounded event localization for stronger video temporal modeling.
This is the weight repository for Qwen3-VL-4B-Instruct.
Model Performance
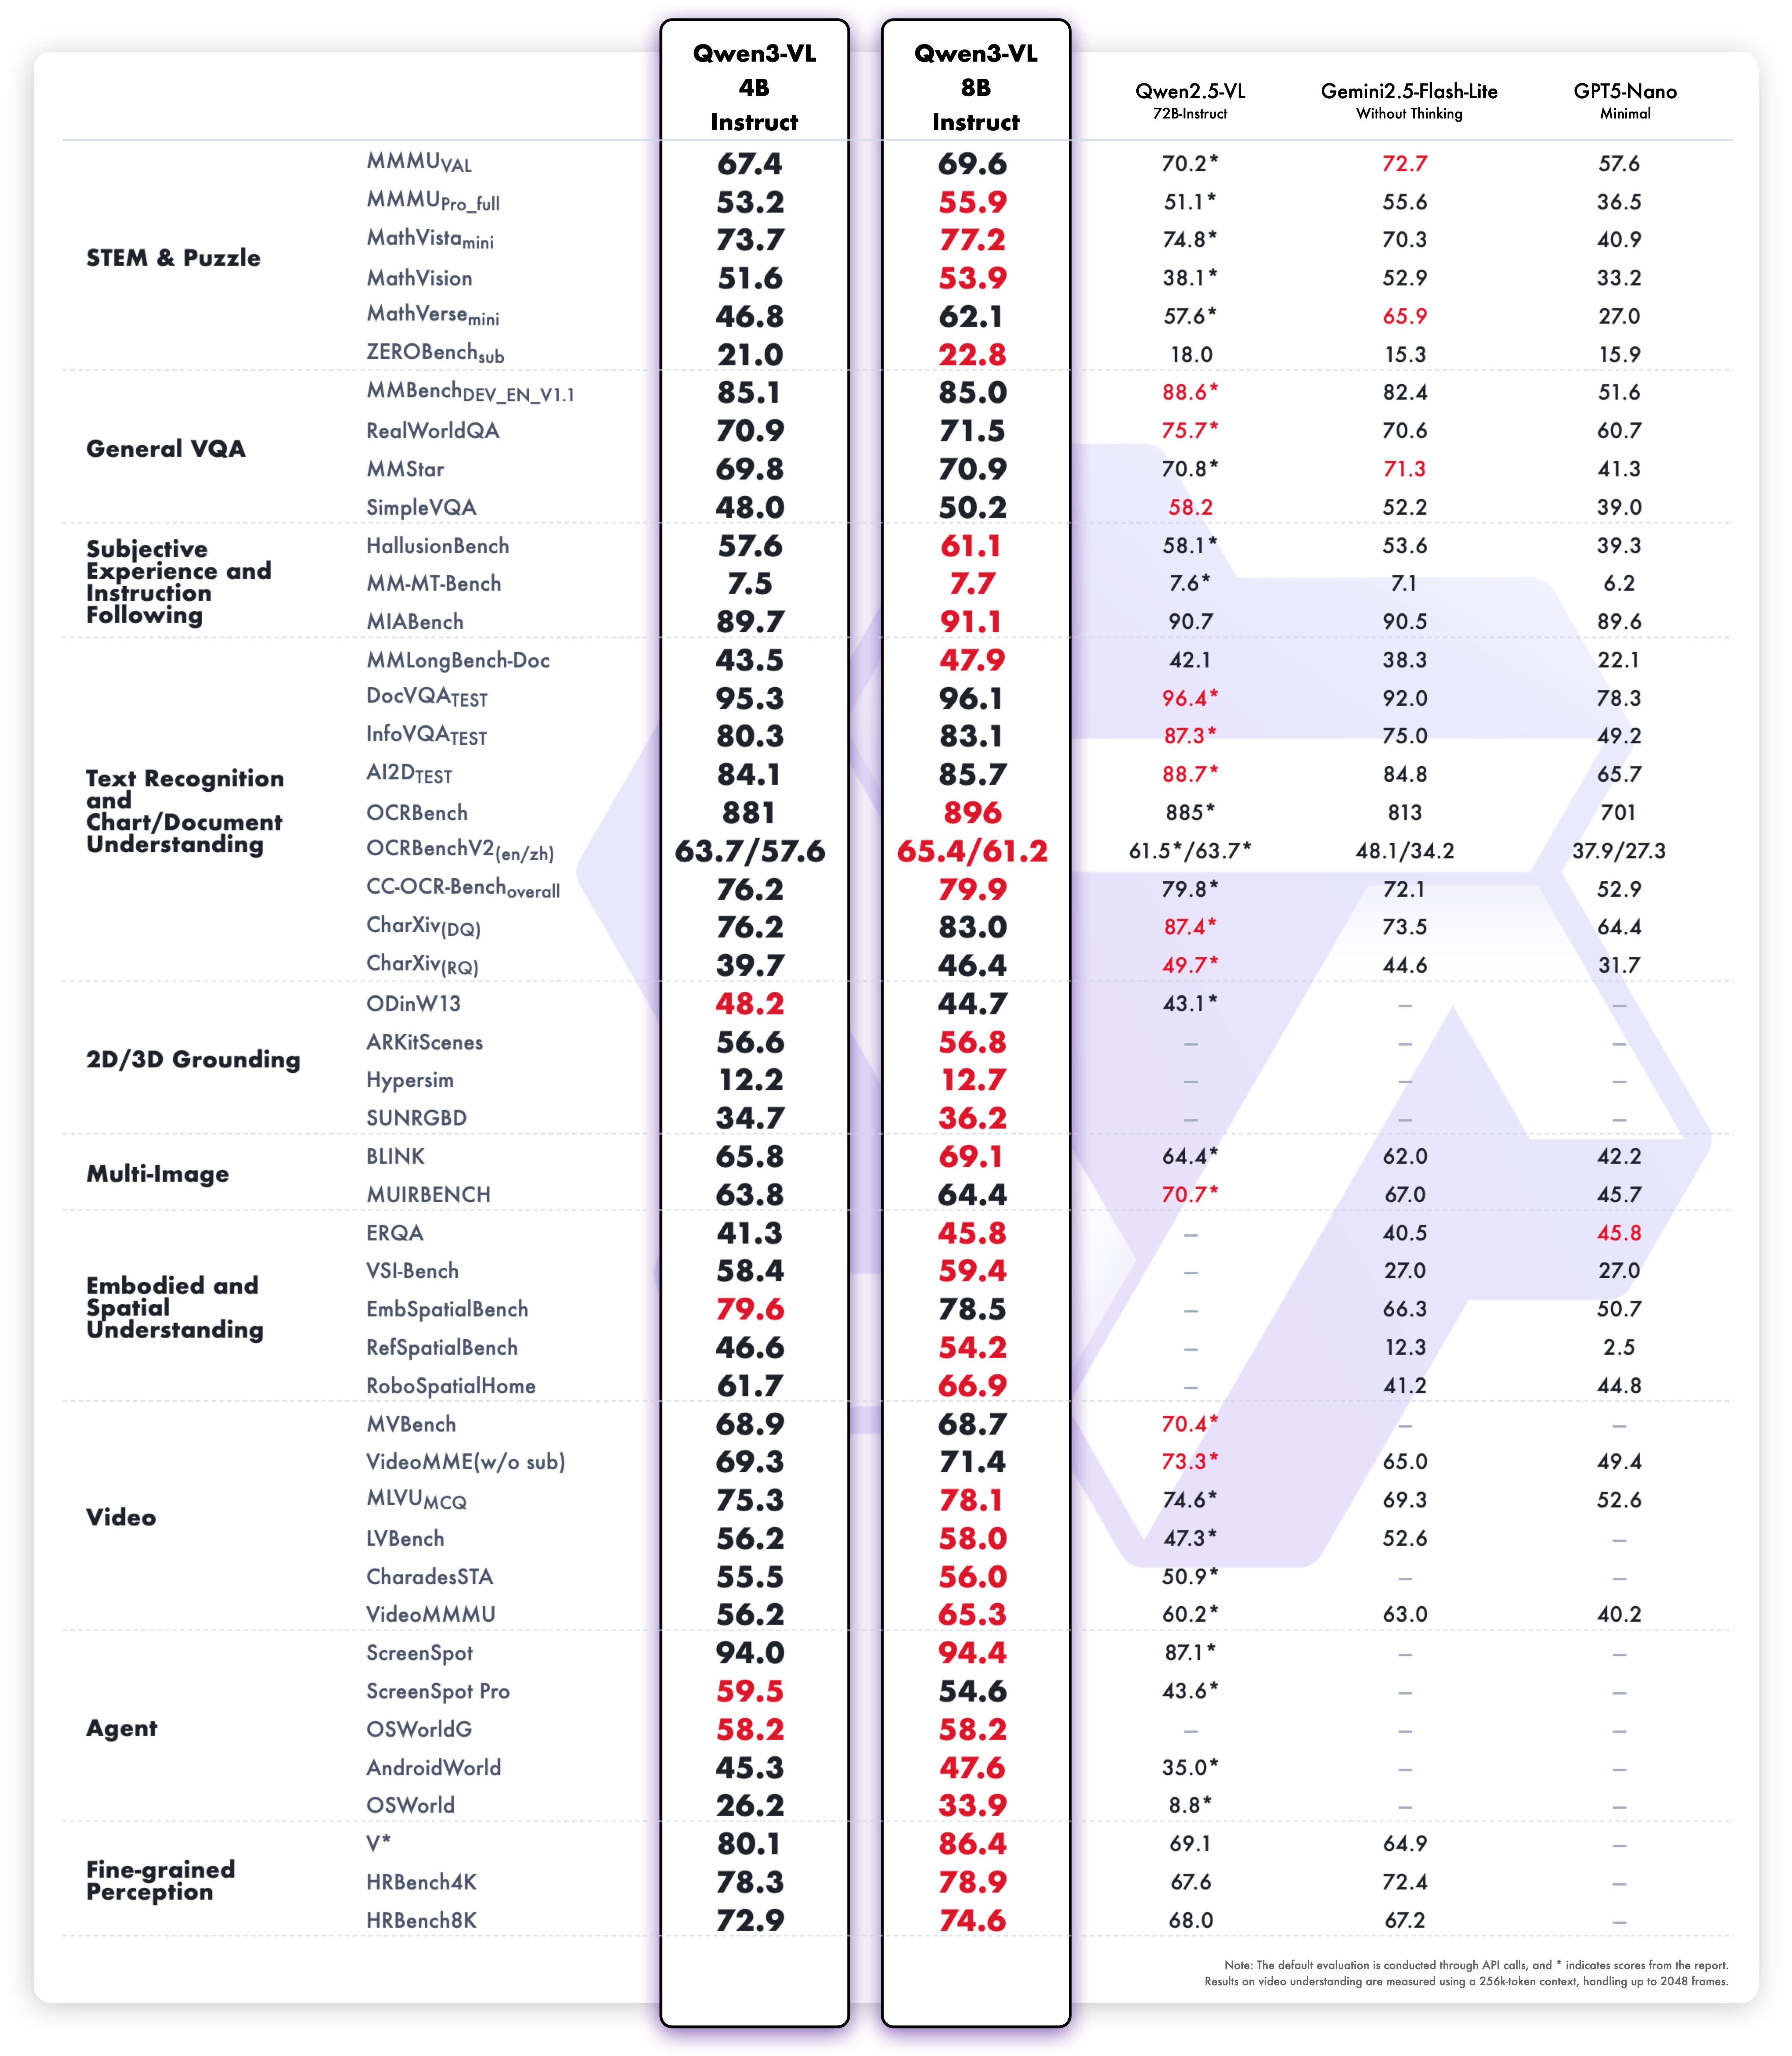
Multimodal performance
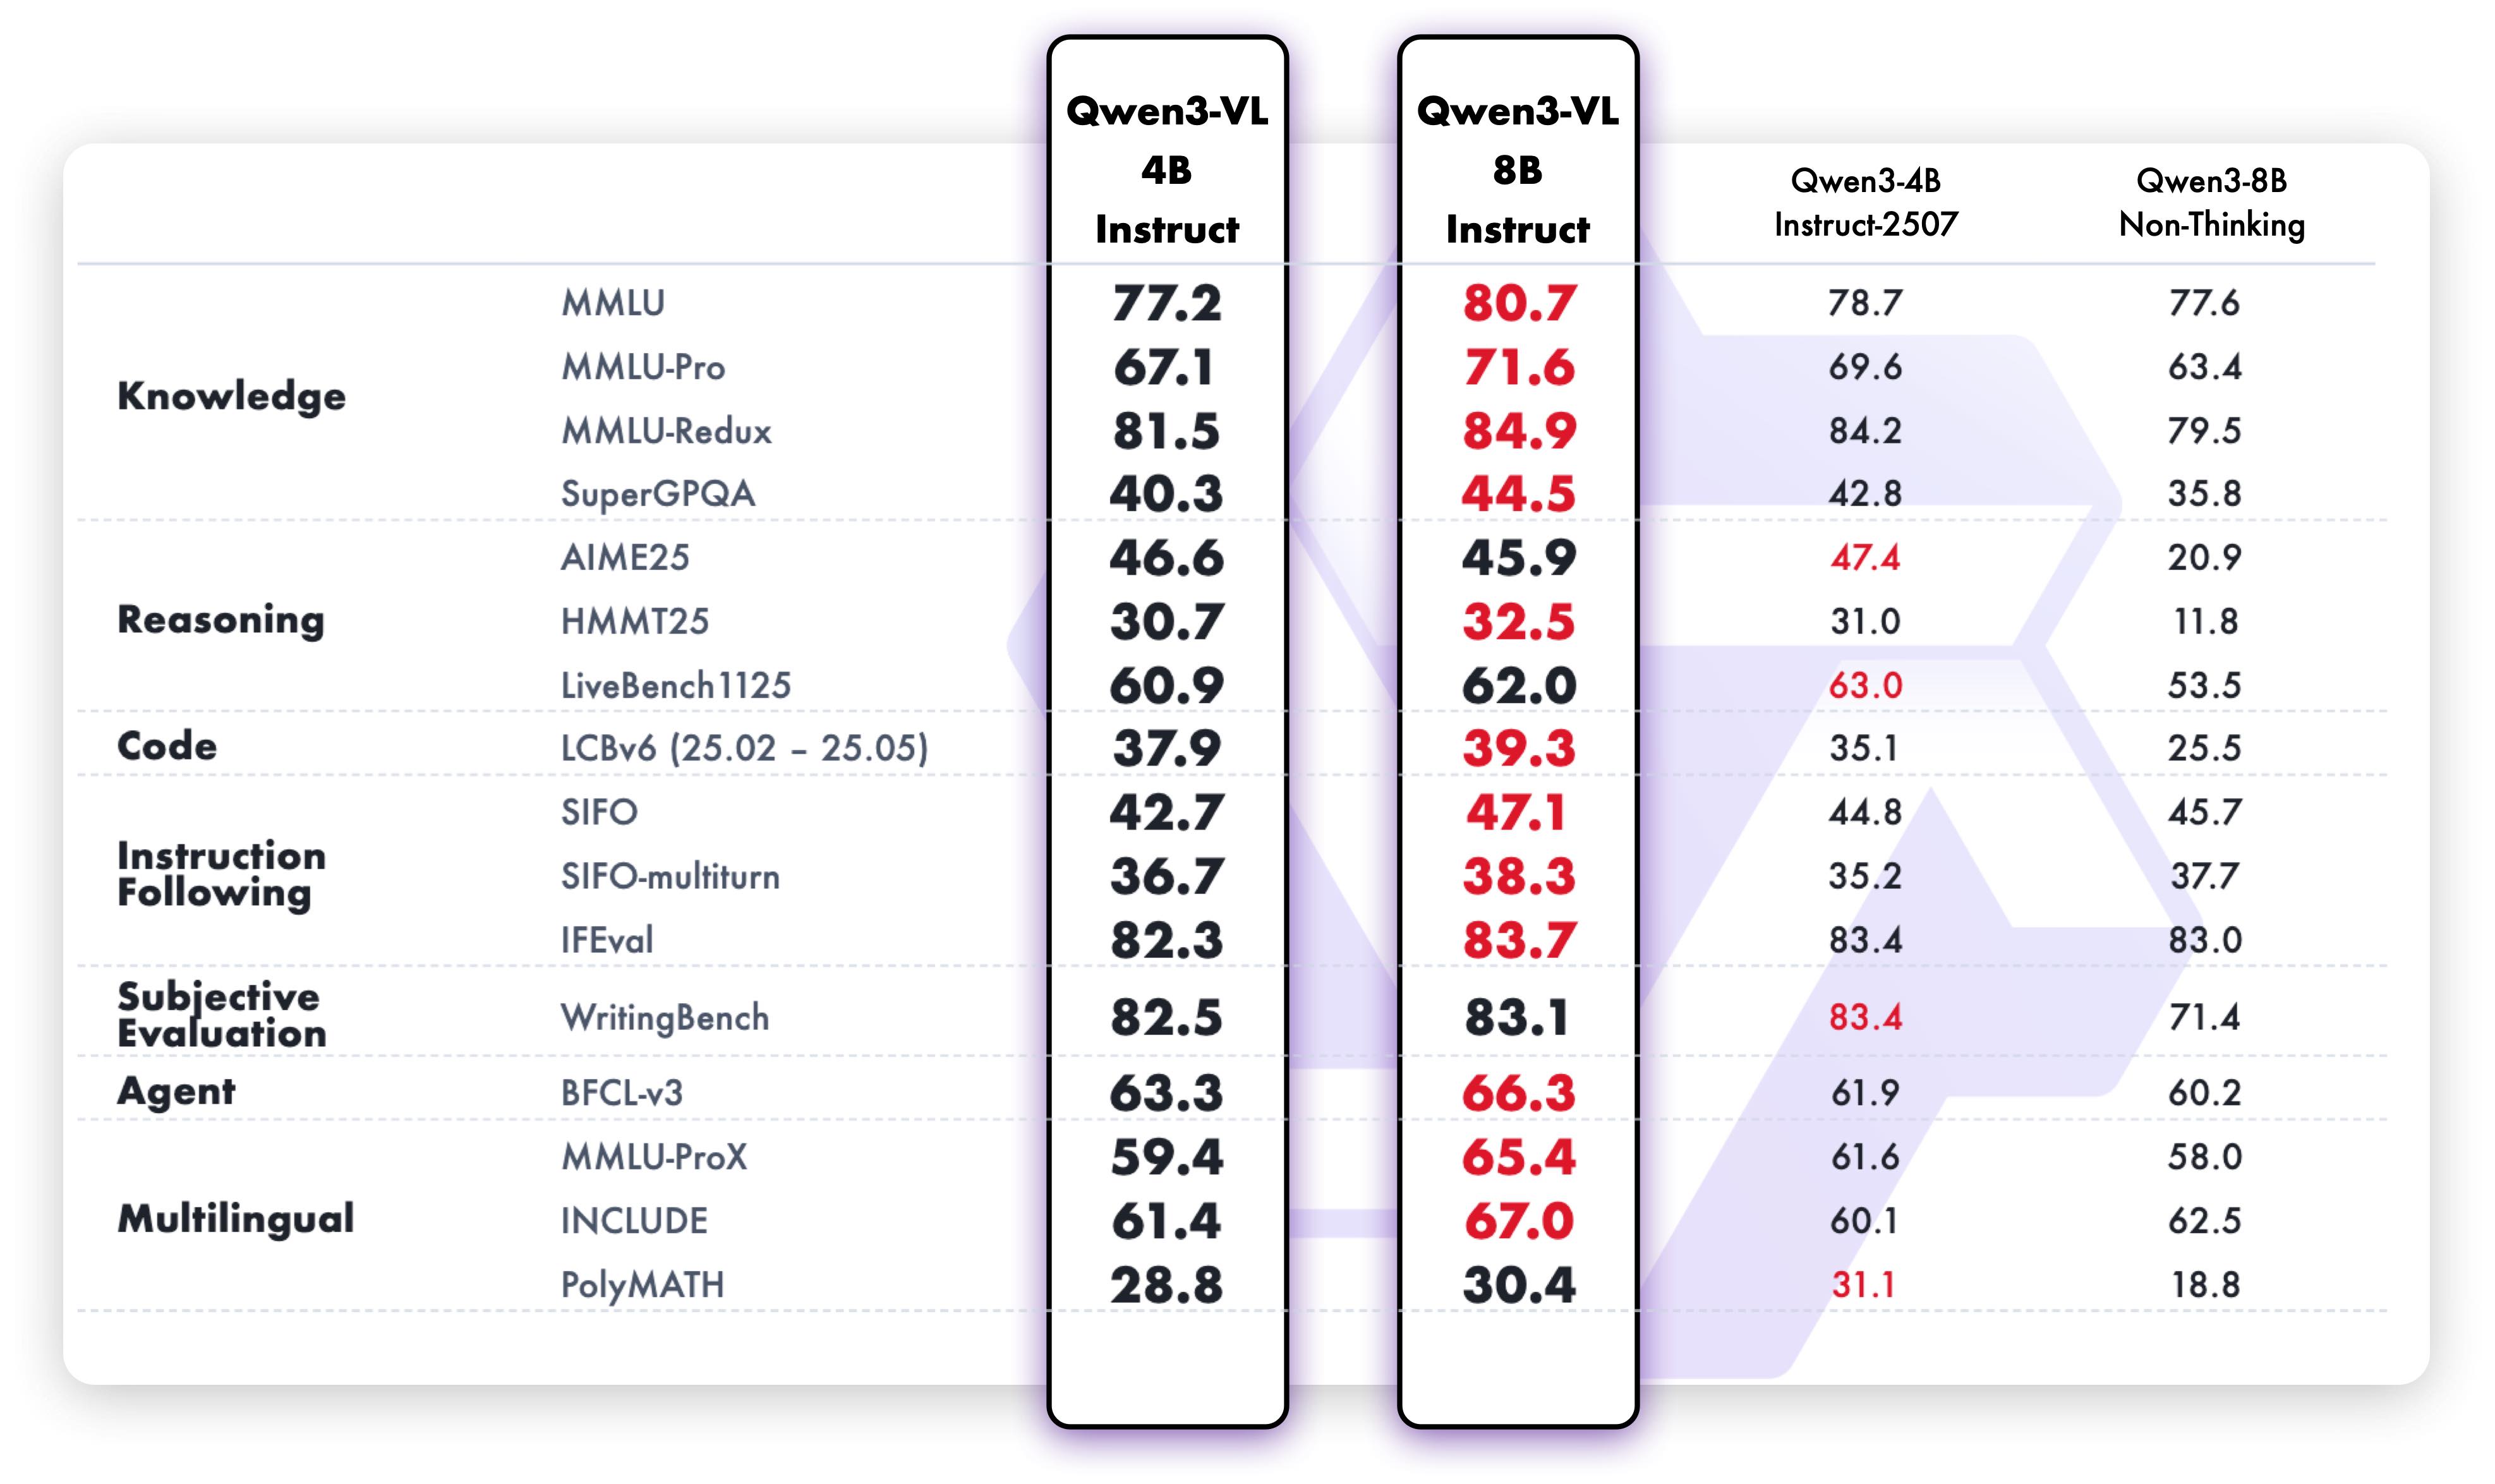
Pure text performance
Quickstart
Below, we provide simple examples to show how to use Qwen3-VL with 🤖 ModelScope and 🤗 Transformers.
The code of Qwen3-VL has been in the latest Hugging Face transformers and we advise you to build from source with command:
pip install git+https://github.com/huggingface/transformers
# pip install transformers==4.57.0 # currently, V4.57.0 is not released
Using 🤗 Transformers to Chat
Here we show a code snippet to show how to use the chat model with transformers:
from transformers import Qwen3VLForConditionalGeneration, AutoProcessor

# default: Load the model on the available device(s)
model = Qwen3VLForConditionalGeneration.from_pretrained(
    "Qwen/Qwen3-VL-4B-Instruct", dtype="auto", device_map="auto"
)

# We recommend enabling flash_attention_2 for better acceleration and memory saving, especially in multi-image and video scenarios.
# model = Qwen3VLForConditionalGeneration.from_pretrained(
#     "Qwen/Qwen3-VL-4B-Instruct",
#     dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )

processor = AutoProcessor.from_pretrained("Qwen/Qwen3-VL-4B-Instruct")

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image",
                "image": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg",
            },
            {"type": "text", "text": "Describe this image."},
        ],
    }
]

# Preparation for inference
inputs = processor.apply_chat_template(
    messages,
    tokenize=True,
    add_generation_prompt=True,
    return_dict=True,
    return_tensors="pt"
)
inputs = inputs.to(model.device)

# Inference: Generation of the output
generated_ids = model.generate(**inputs, max_new_tokens=128)
generated_ids_trimmed = [
    out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text)
Generation Hyperparameters
VL
export greedy='false'
export top_p=0.8
export top_k=20
export temperature=0.7
export repetition_penalty=1.0
export presence_penalty=1.5
export out_seq_length=16384
Text
export greedy='false'
export top_p=1.0
export top_k=40
export repetition_penalty=1.0
export presence_penalty=2.0
export temperature=1.0
export out_seq_length=32768
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen3technicalreport,
      title={Qwen3 Technical Report},
      author={Qwen Team},
      year={2025},
      eprint={2505.09388},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.09388},
}

@article{Qwen2.5-VL,
  title={Qwen2.5-VL Technical Report},
  author={Bai, Shuai and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Song, Sibo and Dang, Kai and Wang, Peng and Wang, Shijie and Tang, Jun and Zhong, Humen and Zhu, Yuanzhi and Yang, Mingkun and Li, Zhaohai and Wan, Jianqiang and Wang, Pengfei and Ding, Wei and Fu, Zheren and Xu, Yiheng and Ye, Jiabo and Zhang, Xi and Xie, Tianbao and Cheng, Zesen and Zhang, Hang and Yang, Zhibo and Xu, Haiyang and Lin, Junyang},
  journal={arXiv preprint arXiv:2502.13923},
  year={2025}
}

@article{Qwen2VL,
  title={Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution},
  author={Wang, Peng and Bai, Shuai and Tan, Sinan and Wang, Shijie and Fan, Zhihao and Bai, Jinze and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Fan, Yang and Dang, Kai and Du, Mengfei and Ren, Xuancheng and Men, Rui and Liu, Dayiheng and Zhou, Chang and Zhou, Jingren and Lin, Junyang},
  journal={arXiv preprint arXiv:2409.12191},
  year={2024}
}

@article{Qwen-VL,
  title={Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond},
  author={Bai, Jinze and Bai, Shuai and Yang, Shusheng and Wang, Shijie and Tan, Sinan and Wang, Peng and Lin, Junyang and Zhou, Chang and Zhou, Jingren},
  journal={arXiv preprint arXiv:2308.12966},
  year={2023}
}
More from Qwen (Alibaba)
On Hugging Face
Everything on this page comes from these pages and is refreshed every few hours; Hugging Face always has the latest.